
Why I stopped counting
The number game nobody can win
I build a small memory engine for AI agents. And I keep running into the same wall. Every memory product quotes one accuracy number. 90 percent. 94 percent. 96 percent. Every time I try to put two of them side by side, I can't, because each one was measured with a different model grading the answers, on a different version of the test. Some of those numbers aren't even "did it answer correctly". They are "did it find the right document", which is a different thing wearing the same costume.
So I stopped trying to win the number game, and I asked a smaller, more honest question. It is the only question where a memory layer actually has to earn its keep.
The setup
First, the library
Picture a library. You walk up with a question. A librarian goes to the shelves, brings you back a few pages, you read them, and you answer. Almost everything in agent memory is some version of that librarian. There are two librarians I care about here.
The first one is lazy. When you ask a question, she just hands you the last few pages you happened to read. No thought about whether they are relevant. That is a "recency window": keep the most recent slice of the conversation and hope the answer is in there.
The second one is smart. She has actually read your whole history, and she brings you the few pages that actually answer the question, even if you talked about it months ago. That is what our memory layer does: it selects.
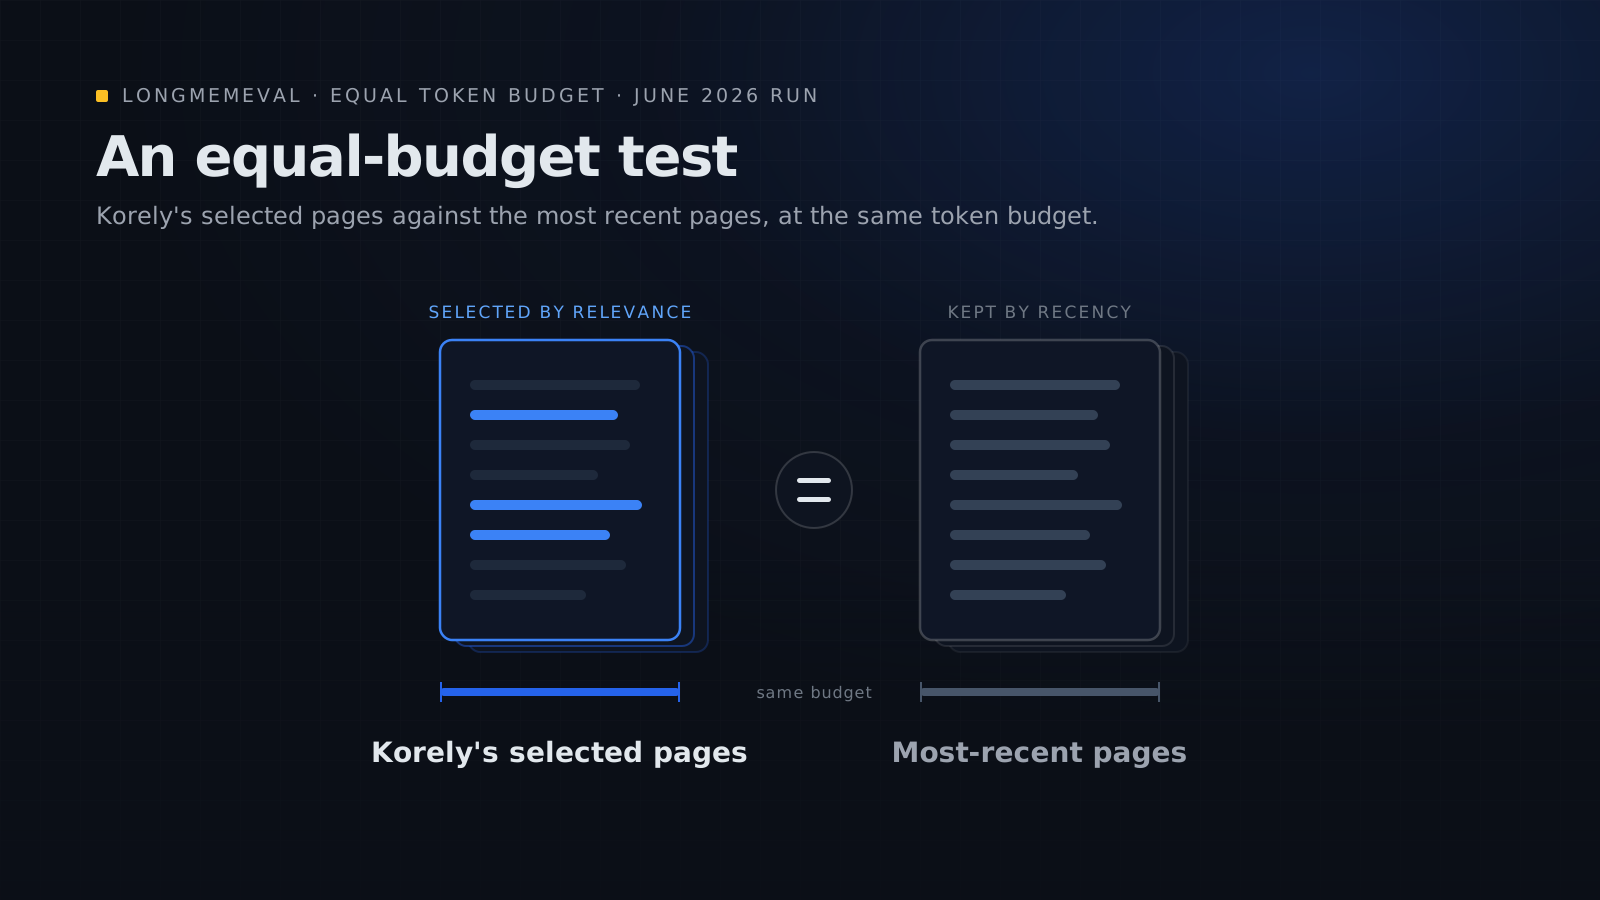
Now the trick that makes the test fair. I let both librarians bring you the same number of pages. Same size stack. If the smart librarian could only win by handing you a thicker pile, she wouldn't have proven anything, she'd just be spending more. So I fix the budget and the only thing that can differ is which pages they picked.
The person reading those pages and writing the answer is an AI model. I call it the student. A second AI, the judge, checks the student's answer against the correct one. Same student, same judge, for both librarians. That way, if the student or the judge has any quirk, it hits both sides equally and cancels out.
The run
What the June run measures
The June run uses a public benchmark called LongMemEval: 178 questions about long, multi-session chats. Both librarians get the same token budget, roughly a couple of pages.
The score is the share of questions the student answers correctly from each librarian's pages. This page no longer quotes the June scores: the note at the top explains why.
The test is built to show where a recency window breaks. The lazy librarian does fine when the answer is in something you just talked about. She cannot help when the answer lives in an old session (how many times did this happen, what did you say three months ago), because the recent pages simply don't reach back that far.
Is it real, or did we get lucky?
Ruling out luck, in three tools
178 questions is a small class. Maybe the smart librarian just gets lucky on a handful of them. Before anyone claims anything, that has to be ruled out. There are three standard tools for it. Here is each one, explained as if you have never seen it.
Tool 1: the p-value
Imagine the two librarians were secretly equally good. Even then, luck alone would sometimes make one look a bit better, the same way flipping two coins won't always give the same number of heads. The p-value is the probability that luck alone, between two librarians who are really the same, would produce a gap at least as big as the one actually measured. A tiny p-value means luck basically never does this, so the gap is real. One way to write it is to add up the chance of every outcome at least as lopsided as ours, treating each disagreement like a coin flip:
Tool 2: McNemar's test
Both librarians answer the exact same 178 questions. Some questions are just easy (both get them right) and some are just hard (both miss them). Those tell you nothing about who is better. So McNemar's test throws away every question the two agreed on, and looks only at the disagreements. If the two were truly equal, each disagreement should be a 50/50 coin flip. Here b is the number of disagreements the smart librarian wins, c the number the lazy one wins:
The top is the gap between the two win counts, minus 1, squared; the bottom is the total number of disagreements. The bigger the value, the harder it is for luck alone to explain a split that lopsided.
Tool 3: the confidence interval
Any score measured on 178 questions is a best guess from those particular questions. A different 178 would wobble a little. A confidence interval is the honest range around the guess: I'm 95 percent sure the true number sits between these two values. The standard recipe for a percentage is the Wilson interval. It looks busy, but every piece is just "the measured rate, nudged toward the middle and widened a bit because the sample is finite":
The rate is the measured percentage, n the number of questions, and z a fixed constant (1.96) that pins it to 95 percent sure. When the ranges of two systems do not overlap, the particular sample of questions cannot explain the difference between them.
The ceiling
How close is "just hand me the whole library"?
You might be thinking: forget selecting, just give the student every page. The June run measures that too, as a ceiling. The point is never that selecting beats reading everything. It's that you almost never can read everything (there's too much) or want to (it's slow and expensive). That is why Korely's context block has a token budget you set, 800 tokens by default: however long the history gets, the block stays within it.
The honest part
Why I refuse to quote a single magic number
Here is the reason I lead with the gap and not with a hero number. The score depends on the student. Swap Gemini Flash for GPT-4o, a stronger and more careful model, and the very same pages can get a different score.
That does not mean the memory got worse. The pages are identical. What changes is the student. Under the instruction "say I don't know if the answer isn't clearly there", a more cautious student raises its hand less, so it scores lower, on the same pages.
The absolute is a property of the student you happen to use. The gap at an equal budget, with the same student and the same judge on both sides, is what says something about the memory. This is exactly why the 90 something numbers floating around the field aren't comparable. A number with no student, no judge, and no version of the test attached can't be checked, so it can't really be believed.
A tool you can keep
Three questions for any memory number you see
You don't need anyone to name names. You just need three questions to audit any number:
1. Which student read the pages? A stronger reader
inflates every score.
2. Which judge graded it? A lenient grader, or one
grading its own answers, quietly lifts the number.
3. Which version of the test? Handing the student the
right session up front is a much easier exam than burying it in hundreds
of irrelevant ones. And some headline numbers aren't "did it answer",
they're "did it retrieve", which is not the same exam at all.
Ask those three and most leaderboard numbers turn into "measured under conditions nobody wrote down". The same three questions apply to every number we publish.
Under the hood
What the librarian keeps in her notebook
Finding the right pages is one job. Knowing what's related to what is another. Our librarian keeps an index of which pages mention which people, tools, and topics. So when you ask "what else touches this?", she follows the index, instead of squinting at titles and searching again.
And the thing that makes her smart isn't a bigger pile of paper. It's that she keeps a notebook of facts, and every fact knows when it became true and when she learned it. When a new fact contradicts an old one (you used to charge 9.99, now you charge 19), she crosses out the old one instead of keeping both and confusing you. It runs on plain Postgres, in the EU with Korely Cloud or on your own servers with Self-hosted, and the notebook is yours. It's the difference between a drawer stuffed with every receipt you ever got, and a notebook someone actually kept up to date.
Reproduce it
Run it yourself
The method lives in one open repository, with the saved per-question results of the June run kept there as a record, with a note that says the same as the one on this page. Both defects are options of its accuracy script now: one sets the cap on the answer, the other gives each question its date.
github.com/verdana86/korely-graphrag
The selected pages of the June run come from Korely's hosted memory: the context block the API gave in June 2026, which has changed since. In agent memory, the honest unit of progress isn't a big accuracy number. It's the gap at an equal budget, measured with a stated student, a stated judge, and a stated test, and reproducible by a stranger. That standard applies to us too: the June run does not meet it, so its numbers are withdrawn.